News
Jev by TypeSafe AI: System One Models and the Startup Playbook for Cheap, Fast Decisions (2026)
Jev is TypeSafe AI's System One model that returns typed decisions with calibrated probabilities in ~200ms for pennies ($0.042/MTok). Here is how startups use it for high-volume routing, scoring, agent guardrails, Vercel AI Gateway instant access, and hybrid architectures.

Contents (11)
- Key Facts: TypeSafe AI and Jev
- What Is Jev? The Mechanics of a System One Model
- Why Startups Care: The Unit Economics of Cheap Decisions
- What the Developer Community and Hacker News Concluded
- High-Value Startup Use Cases: Where Jev Fits
- Architecture Pattern: The Hybrid "Traffic Cop + Specialist" Stack
- How to Get Access Today (Including the Immediate Bypass)
- Honest Counterweight: Limitations and When Not to Use Jev
- The Founder's 6-Step Implementation Checklist
- Accelerate Your Startup on SaaSCity
- Frequently Asked Questions
Updated September 19, 2026 with production startup use cases, Vercel AI Gateway access patterns, community benchmarks, and live browser captures.
Quick answer: TypeSafe AI emerged from stealth on September 15, 2026, with a $40 million seed round led by DCVC and an unconventional model called Jev. Jev is a dedicated System One decision engine. It does not generate text, summaries, code, or conversational banter. Instead, you feed it application state (raw text, JSON, or arrays) alongside predefined typed questions. Jev returns schema-constrained decisions (probabilities, multiple-choice selections, and rubric scores) in 70 to 500 milliseconds for $0.042 per million input tokens, with output tokens unmetered and free. For startups running high-volume queues, this turns what used to be expensive, fragile LLM prompt wrappers into fast, dependable code branches.
The common operational pattern emerging across early founder teams is straightforward: find an expensive queue of incoming information in your business and place Jev at the front of it.
Key Facts: TypeSafe AI and Jev
| Attribute | Details |
|---|---|
| Official Launch | September 15, 2026 (Early Access) |
| Founding Team | Diogo Almeida (CEO, ex-OpenAI RLHF / InstructGPT researcher), Erik Gafni (CTO), Sasha Sheng (COO) |
| Funding | $40 million seed round led by DCVC |
| Model Category | System One Decision Engine (non-generative) |
| Input Pricing | $0.042 per million tokens ($42 per billion tokens) |
| Output Pricing | Free (outputs are typed values, not token streams) |
| Median Latency | 70ms to 500ms (typically ~200ms in production) |
| Supported Primitives | Noul (Boolean probability), Choice (Categorical), Score (Ordinal rubric) |
| Naming Origin | William Stanley Jevons (Jevons paradox: cheaper intelligence drives higher consumption) |
| Direct Access | TypeSafe Waitlist (typesafe.ai) or Vercel AI Gateway (typesafe-ai/jev) |
What Is Jev? The Mechanics of a System One Model
To understand Jev, it helps to recall Daniel Kahneman's cognitive framework in Thinking, Fast and Slow. Human cognition relies on two systems: System 1 (fast, automated, pattern-matched intuition) and System 2 (slow, deliberate, analytical calculation).
Over the past three years, the software industry has deployed heavy System 2 machinery for simple System 1 chores. Startups regularly pay $0.50 to $5.00 per million tokens to frontier LLMs just to classify whether a support ticket is about billing, whether a lead is qualified, or which internal API to trigger next.
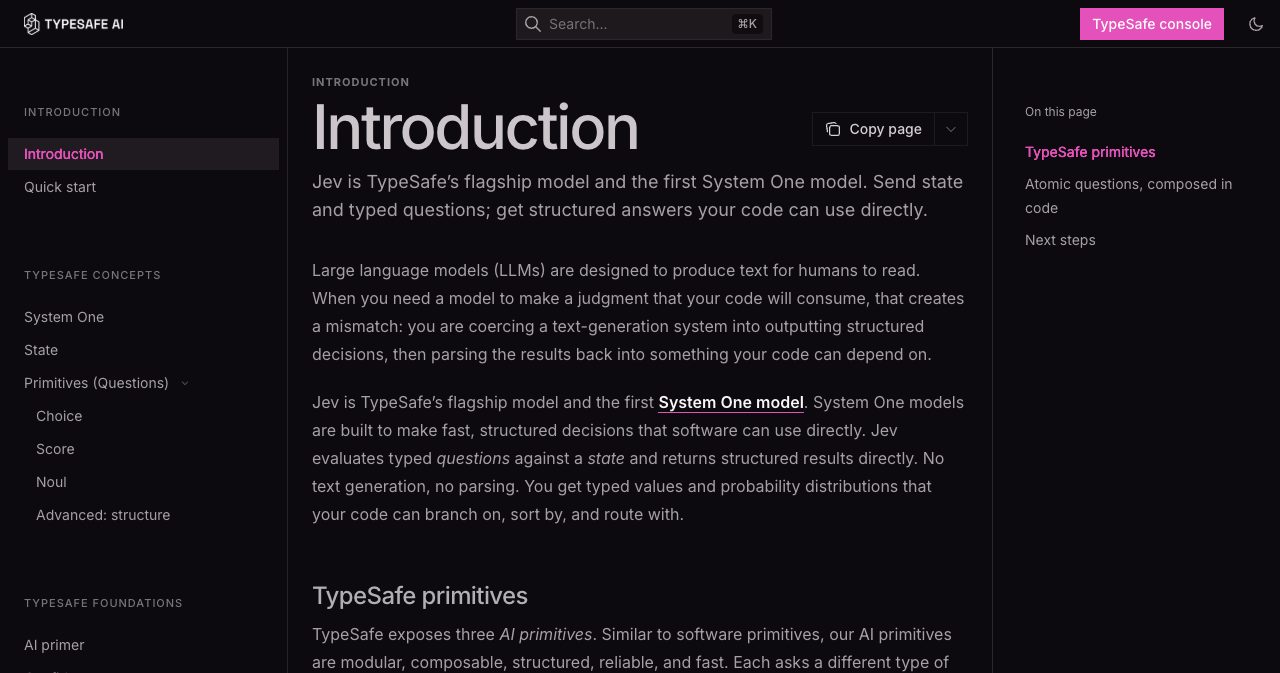
Jev is built specifically for System 1 tasks. It strips away autoregressive text completion entirely.
The Three Decision Primitives
TypeSafe provides three core primitives in the Jev API. You can evaluate dozens of these primitives in parallel within a single HTTP request:
- Noul (Calibrated Yes/No): Evaluates the probability (from 0.0 to 1.0) that a statement is true relative to the provided state. Unlike LLM logprobs, which measure token likelihood rather than factual truth, Noul probabilities are calibrated so that a 0.8 score corresponds to an 80% empirical accuracy rate.
- Choice (Categorical Selection): Selects one option from an explicit list of up to 255 developer-defined candidates. Jev returns the selected item, the full probability distribution across all choices, and a calibrated confidence metric.
- Score (Ordinal Rubric Rating): Rates the input against a developer-defined scale (such as 1 to 5 stars, or tiers from "Low" to "Critical"). It returns the chosen tier, the confidence score, and adjacent probabilities.
How Parallel Sampling Works
Standard LLMs generate output token by token. If an LLM needs to return a 50-token JSON object, it performs 50 sequential network passes through its transformer layers. That sequential decoding is the mechanical reason frontier models take anywhere from 1.5 to 15 seconds to return a simple routing verdict.
Jev uses what TypeSafe calls a parallel sampler. When you submit application state with five distinct questions, the model evaluates the entire set in a single forward pass. This drops response times down to 70 to 500 milliseconds, fast enough to sit directly inside synchronous user-facing API paths.
The Mental Model: An AI Traffic Cop
The cleanest mental model for Jev is a smart if-statement or an automated traffic cop. It does not replace your primary application code or your generative models. It sits upstream of them. It absorbs noisy, unstructured data, makes an instant judgment, and routes the transaction to the proper destination.
Why Startups Care: The Unit Economics of Cheap Decisions
For an early-stage company, model selection directly dictates gross margins and product viability. Running a GPT-6 Astra or Claude Fable 5.1 call on every inbound event quickly drains a startup's runway.
Pricing Math: $0.042 per Million Tokens
TypeSafe prices Jev at $0.042 per million input tokens ($42 per billion). Output tokens are not billed because the response consists of typed scalar values rather than generated text.
Consider the math on real production workloads:
- A customer support ticket with 1,000 tokens of context costs $0.000042 (about 0.004 cents).
- Classifying 1,700 full email conversations costs roughly 18 cents.
- One startup founder reported that a initial $5 credit lasted through two full days of stress testing, while an agency scoring contact-form leads estimated a $10 deposit would cover three months of production traffic.
| Model / Architecture | Input Price (per MTok) | Output Price (per MTok) | Typical Latency | Output Guarantee |
|---|---|---|---|---|
| TypeSafe Jev | $0.042 | Free (0.00) | 70-500 ms | Guaranteed schema adherence (typesafe) |
| GPT-6 Astra | $0.20 to $1.25 | $1.00 to $5.00 | 2,000-8,000 ms | Markdown/JSON parsing required |
| Claude Fable 5.1 | $0.25 to $2.00 | $1.25 to $7.50 | 1,800-6,500 ms | Markdown/JSON parsing required |
| DeepSeek V4-Flash | $0.08 to $0.15 | $0.30 to $0.60 | 600-1,800 ms | JSON mode with occasional retry loops |
The Jevons Paradox in Software
TypeSafe named its model after William Stanley Jevons, who observed that increasing the efficiency of coal consumption did not reduce overall coal demand; it increased it by making steam engines economical for thousands of new industries.
The same dynamic applies to AI decisions. When an inference call costs $0.02 and takes 3 seconds, you can only afford to evaluate high-priority actions, such as generating an email reply. When an inference call costs $0.00004 and takes 150 milliseconds, you can afford to evaluate every incoming event, every search query, every database row change, and every UI button click.
Addressing the Vendor Benchmarks
TypeSafe's launch announcement claimed Jev is 193.6x faster and 444.6x cheaper than frontier models on decision tasks. It is important to look at how those tests were structured.
TypeSafe's workflow benchmarks on evals.typesafe.ai used the average consensus of GPT-6 Astra and Claude Fable 5.1 as the reference ground truth. TypeSafe disclosed that this methodology inherently favors the models that defined the answer key. Independent developer checks confirm the latency and cost advantages, while noting that classification agreement hovers closer to 67.8% on nuanced or ambiguous text. Treat vendor multipliers with healthy skepticism, but recognize that the mechanical cost and latency advantages are genuine.
What the Developer Community and Hacker News Concluded
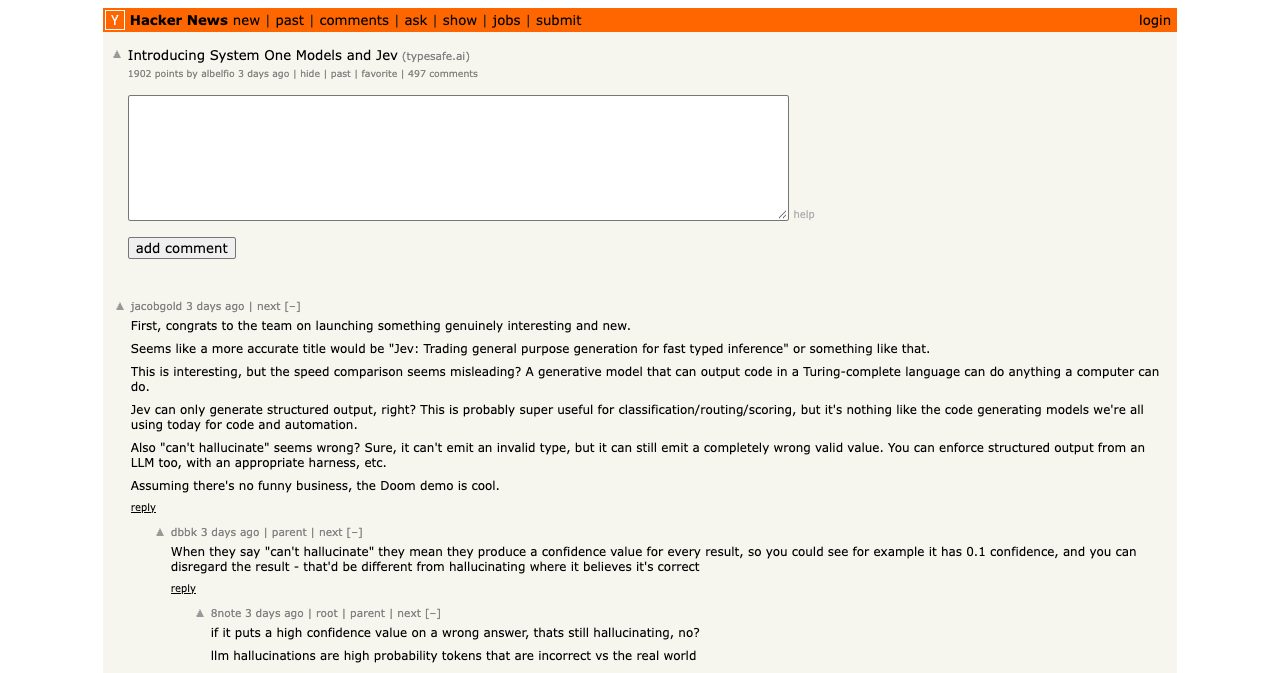
The launch discussion on Hacker News drew 1,537 points and more than 430 comments, offering a balanced view of where Jev excels and where founders should remain cautious.
Core Criticisms from the Community
- Apples-to-Oranges Latency Claims: Commenters noted that comparing a model returning three typed values against an LLM generating hundreds of tokens of text is misleading. While true, that comparison reflects how startups actually misuse LLMs when they only need a classification.
- Proprietary Marketing Terminology: Terms like "RLCD" (Reinforcement Learning for Calibrated Decisions) and "parallel sampler" were introduced without accompanying peer-reviewed academic papers.
- Absence of Third-Party Evals: The only public accuracy evaluations at launch were published by TypeSafe itself.
Pragmatic Takeaways for Founders
Despite marketing skepticism, consensus emerged around the core utility:
- Community estimates suggest that 40% to 70% of LLM calls in typical production pipelines are actually classification, routing, or scoring tasks that do not require text generation.
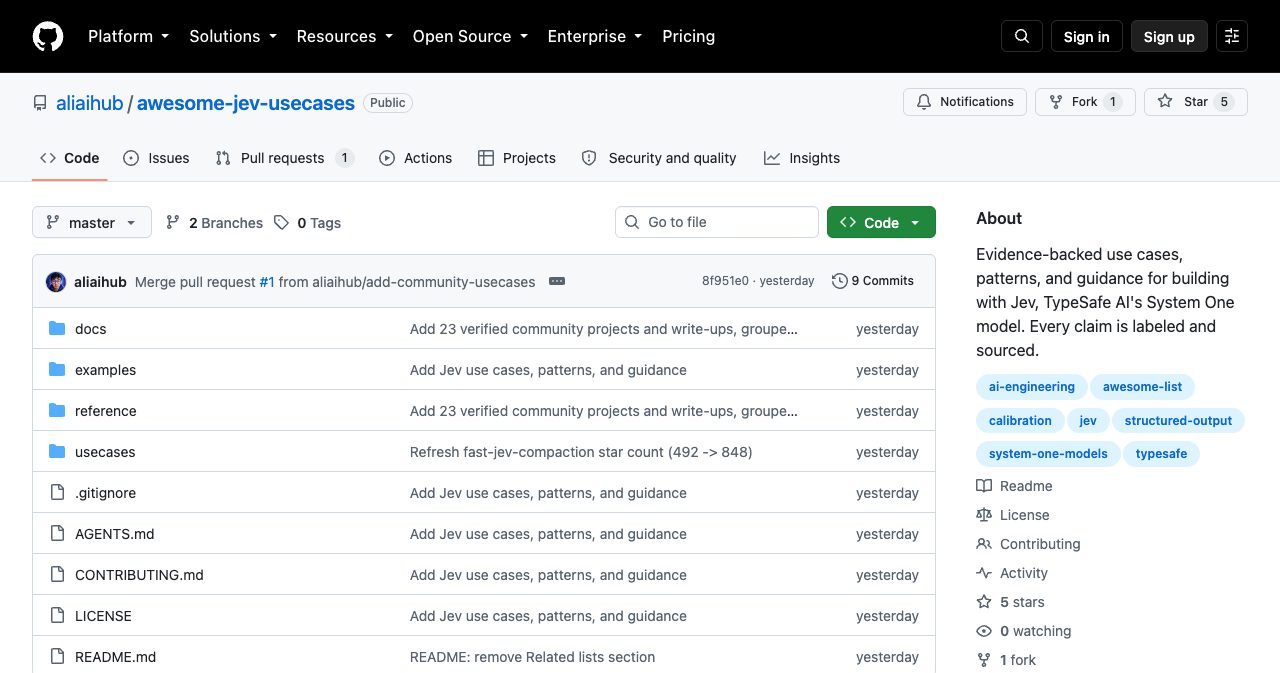
- Within hours of launch, developers released community wrappers, including
dspy-typesafeify, enabling teams to route DSPy signatures directly to Jev for support classification. - When asked why Jev does not write code, CEO Diogo Almeida explained that software development is primarily a problem of state engineering rather than text generation. TypeSafe deliberately chose to automate clear, well-scoped decisions before attempting complex, ambiguous reasoning tasks.
High-Value Startup Use Cases: Where Jev Fits
The founders extracting the most value from Jev focus on high-volume queues where latency, cost, and strict schema adherence matter most.
1. Customer Support and Ticket Routing
In customer operations, every incoming ticket requires triage before any response can be drafted. A single 200ms Jev call can extract three critical attributes:
- Urgency (Score): Rates customer frustration and account risk on a 1-to-5 scale.
- Category (Choice): Classifies the issue into Billing, Bug Report, Feature Request, or Security.
- Enterprise Escalation (Noul): Determines whether the inquiry requires an immediate human account manager.
Because the output arrives as typed primitives, your backend can execute deterministic webhook routing instantly. If a ticket is low-complexity, Jev routes it to an automated macro. If it requires a tailored response, Jev routes it to a frontier LLM or human agent with pre-populated tags.
2. Inbound Lead Qualification and Instant Dispatch
For B2B SaaS and marketplace platforms, lead response speed determines conversion rates:
- ICP Scoring: When a prospect submits a contact form, Jev scores company size, intent signals, and budget indicators against your qualification rubric.
- Instant Matching: In service marketplaces (such as home repair or freelance platforms), Jev matches user project descriptions against provider specialty lists using the Choice primitive, generating instant matches in under 300 milliseconds.
3. Operational "What Now?" Queues
Every business features operational queues where employees spend hours reviewing incoming items and picking the next action. These are natural targets for Jev:
- Recruitment: Screen incoming resumes against structured criteria, outputting decisions to advance, request portfolio samples, or reject.
- FinTech and Lending: Triage loan applications or transaction alerts into automatic approval, fraud hold, or secondary review.
- Customer Success: Monitor product usage drops and trigger targeted founder outreach when accounts show churn risk indicators.
- E-Commerce Operations: Monitor product return spikes or supplier stock changes to pause ad spend automatically.
4. AI Agent Architecture and Guardrails
Complex agent workflows frequently derail because models struggle to manage their own control flow. Jev stabilizes agent loops in three specific places:
- Tool Selection: Selecting which tool to call next from a defined list of capabilities.
- Loop Termination: Evaluating whether the agent has satisfied the user's objective or should stop.
- Pre-Flight Guardrails: Scanning generated text from an upstream LLM before sending it to a customer, checking for prompt injection artifacts or policy violations.
5. High-Volume Data Operations and Pre-RAG Filtering
In document processing and retrieval-augmented generation (RAG), stuffing hundreds of irrelevant chunks into an LLM context window inflates latency and token costs:
- Document Relevance: Score candidate documentation chunks against a user's question, passing only high-scoring text to the generation model.
- Content Moderation: Filter community submissions for spam, promotion, or policy violations at high volume for pennies per day.
Architecture Pattern: The Hybrid "Traffic Cop + Specialist" Stack
The most reliable way to implement Jev is as an upstream filter in a hybrid architecture. Jev handles volume and classification; code manages policy; frontier LLMs or humans handle nuanced generation.
flowchart TD
    A["Incoming Request (Webhook / Form / Ticket)"] --> B["Jev Decision Engine (~200ms, $0.042/MTok)"]
    B --> C{"Confidence & Urgency Evaluation"}
    C -->|"High Confidence + Standard Action"| D["Deterministic Application Code / Fast Action"]
    C -->|"Complex / Low Confidence"| E["Escalate to Human Specialist"]
    C -->|"Generation Required"| F["Frontier LLM (GPT-6 Astra / Claude Fable 5.1)"]
    F --> G["Optional Jev QA / Safety Verification Pass"]
    G --> H["Deliver Output to User"]
Implementation Example: Node.js / TypeScript
Here is a practical implementation of the hybrid architecture using TypeScript:
import { evaluate } from '@typesafe-ai/sdk'; // or via @ai-sdk/typesafe

interface TriageResult {
  category: 'billing' | 'technical' | 'sales' | 'spam';
  urgencyScore: number;
  needsHumanIntervention: boolean;
  confidence: number;
}

export async function triageInboundTicket(ticketText: string): Promise<void> {
  // Step 1: Run atomic evaluations in parallel with Jev
  const verdict = await evaluate({
    model: 'typesafe-ai/jev',
    state: ticketText,
    questions: {
      category: {
        type: 'choice',
        options: ['billing', 'technical', 'sales', 'spam'],
        description: 'Primary customer intent',
      },
      urgencyScore: {
        type: 'score',
        scale: ['low', 'medium', 'high', 'critical'],
        description: 'Customer frustration level and operational impact',
      },
      needsHumanIntervention: {
        type: 'noul',
        statement: 'This customer is requesting account cancellation or executive escalation.',
      },
    },
  });

  const { category, urgencyScore, needsHumanIntervention, confidence } = verdict;

  // Step 2: Deterministic routing in application code
  if (category.value === 'spam' && confidence > 0.90) {
    await archiveTicket(ticketText);
    return;
  }

  if (needsHumanIntervention.probability > 0.75 || urgencyScore.value === 'critical') {
    await notifyOnCallTeam({ ticketText, urgency: urgencyScore.value });
    return;
  }

  // Step 3: Route to standard automated workflow or frontier LLM
  if (category.value === 'technical') {
    await routeToTechnicalDocsAgent(ticketText);
  } else {
    await draftStandardReply(ticketText, category.value);
  }
}
This pattern guarantees that control flow stays within your own codebase. You avoid fragile multi-turn prompt loops, eliminate schema validation errors, and keep expensive frontier inference calls reserved for requests that actually require them.
How to Get Access Today (Including the Immediate Bypass)
There are two primary ways to access Jev:
1. The Official TypeSafe Waitlist
You can request early access directly on TypeSafe AI's website. Once approved, you receive credentials for console.typesafe.ai, providing an interactive testing playground and API key management. Early access turnaround typically takes one to two business days for technical teams.
2. Immediate Access via Vercel AI Gateway (No Waitlist)
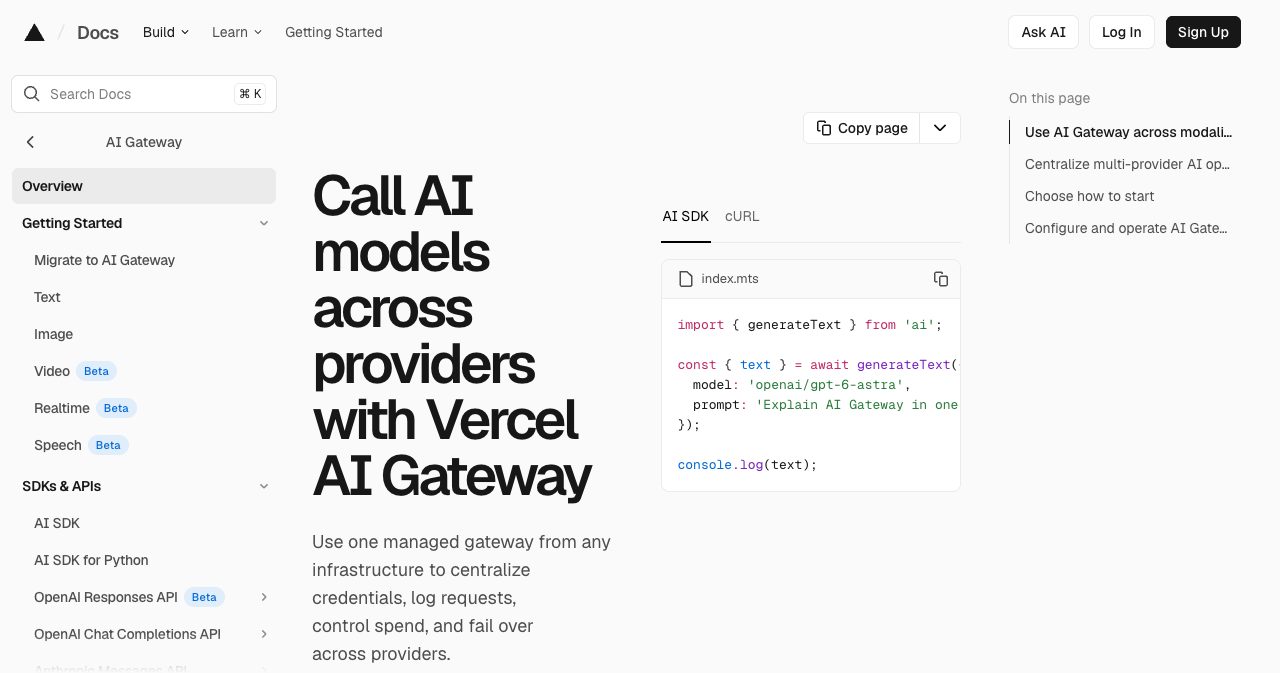
If you want to start testing immediately without waiting for console approval, Jev is available through the Vercel AI Gateway under the model identifier typesafe-ai/jev.
Through Vercel AI SDK 7's evaluate interface, you can point your existing deployment to the gateway and begin evaluating inputs with zero waitlist friction. Token pricing matches TypeSafe's native $0.042/MTok rate.
Rate Limits and Production Constraints
In early access, TypeSafe enforces default limits of approximately 250,000 tokens per second and 1,200 requests per minute (RPM). These limits are sufficient for early-stage production workloads, with higher throughput tiers available for enterprise agreements.
Best Practices for Query Design
When designing queries for Jev, follow these practical rules:
- Decompose Complex Questions: Rather than asking Jev to evaluate a compound issue, break it into three or four atomic questions and combine the returned probabilities in code.
- Keep State Clean: Jev is sensitive to irrelevant context. Strip tracking headers, HTML boilerplate, and unrelated metadata before sending state to the model.
- Avoid Arithmetic and Dates: Do not ask Jev to calculate date differences, sum invoice line items, or count characters. Use plain code for mathematical operations.
Honest Counterweight: Limitations and When Not to Use Jev
Building a resilient architecture requires knowing where a tool breaks. Jev is purpose-built for narrow decision tasks, and applying it outside its domain leads to poor outcomes.
1. It Cannot Generate Text or Explanations
If your product needs an empathetic customer support reply, an article summary, or a code patch, Jev cannot help you. It returns scalar decisions and probabilities only. You will still need frontier models like Claude or GPT for any human-facing prose.
2. "Zero Hallucinations" Is a Schema Guarantee, Not a Fact Guarantee
TypeSafe's promotional materials emphasize zero hallucinations. Technically, Jev cannot hallucinate on schema: it will never return a string when asked for a boolean, nor will it invent options outside your Choice array.
However, this does not prevent the model from confidently selecting the wrong option if your context is ambiguous or contradictory. Calibration reduces this error rate, but careful thresholds are still essential.
3. Literal Comprehension and Indirection
Jev is a literal reader. It struggles with sarcasm, double negatives, complex reasoning chains, and adversarial prompt injections designed to mislead classifiers. High-stakes financial and legal applications must retain human review on borderline confidence scores.
4. Technical Constraints
- Choice Limit: Choice lists are capped at 255 options.
- Modality: Text and JSON input only. Image, video, and audio inputs must be transcribed or preprocessed first.
- Context Window: Context windows sit around 32k to 64k tokens depending on the integration path, which is smaller than the 1M+ token windows of frontier LLMs.
- Vendor Concentration: TypeSafe is an early-stage company. To mitigate platform risk, wrap your decision calls in a lightweight interface so you can swap providers if necessary.
The Founder's 6-Step Implementation Checklist
If you want to test whether Jev can reduce your AI infrastructure costs this week, run this simple audit:
- Audit Your Queues: Identify one to three high-volume queues in your application where incoming data waits for human review or triggers an expensive LLM call.
- Sort Sentence Calls from Decision Calls: Review your prompt repository. If an LLM call ends with "respond strictly in JSON" or relies on retry loops to parse an output, mark it as a decision call candidate.
- Draft 3 to 8 Atomic Questions: Break down the evaluation into clear, single-purpose Noul, Choice, and Score questions.
- Benchmark on Production Samples: Test 100 to 500 recorded production requests through the Vercel AI Gateway or TypeSafe playground, measuring latency, cost, and agreement against your existing baseline.
- Establish Confidence Thresholds: Define clear routing boundaries. High-confidence results (above 0.85) trigger automated actions; borderline results route to human review or frontier LLMs.
- Deploy Behind a Feature Flag: Roll out the Jev-backed decision path to a small percentage of traffic, monitoring error rates before scaling up.
Accelerate Your Startup on SaaSCity
Building software in the modern AI ecosystem requires making smart architectural trade-offs between speed, cost, and reliability. If you are shipping a new SaaS product, developer tool, or AI workflow, SaaSCity gives you visibility in front of active builders and early adopters.
Every approved submission receives an indexable profile and a dofollow backlink once you place the city badge. If you need immediate indexation, Quick Pass ($19.99) guarantees a 24-hour review and listing, plus a dedicated building on our interactive live 3D city map, while Premium Listing ($49.99) includes a dedicated launch post with three sponsored links and priority placement in our Monday launch rotation. You can also submit your product autonomously through our public Model Context Protocol server at /mcp.
Frequently Asked Questions
Is Jev a direct replacement for ChatGPT or Claude?
No. Jev is a non-generative decision engine designed for classification, scoring, and routing. It does not write prose, produce summaries, or generate code. It complements generative LLMs by deciding when, how, and whether to invoke them.
How much does Jev cost in production?
TypeSafe AI charges $0.042 per million input tokens, with output tokens free of charge. For comparison, classifying 1,000 text inputs of typical length costs less than a single penny, making it roughly 80% to 95% cheaper than using frontier LLMs for structured extraction.
Can I try Jev without joining the waitlist?
Yes. You can access Jev immediately via the Vercel AI Gateway using the model identifier typesafe-ai/jev and the Vercel AI SDK evaluate method, with the same token pricing and no waiting period.
Are TypeSafe's speed and cost claims accurate?
TypeSafe's reported 193.6x speedup and 444.6x cost reduction are vendor benchmarks conducted against GPT-6 Astra and Claude Fable 5.1 on decision-shaped tasks. In real-world environments, developers observe sub-250ms latency and dramatic cost savings, though classification accuracy depends heavily on clear, unambiguous prompt design.
Will Jev pricing increase after early access?
TypeSafe's executive team states that inference prices are projected to decrease over time as underlying hardware efficiency improves. However, early access pricing may be partially subsidized to drive adoption, so teams should design modular architectures that can adapt if pricing structures shift.
How does Jev prevent JSON schema errors?
Jev does not generate JSON text that requires client-side parsing. Instead, its internal parallel sampler binds directly to the requested primitive types (Noul booleans, Choice selections, and Score ranks), making malformed types or invalid keys impossible by design.
Get your SaaS in front of founders
List your product on SaaSCity - a permanent listing, real discovery, and a dofollow backlink from a high-DR directory. Free with a badge; upgrade for a building on the live city map.